Bites: one ML idea, one picture, two minutes
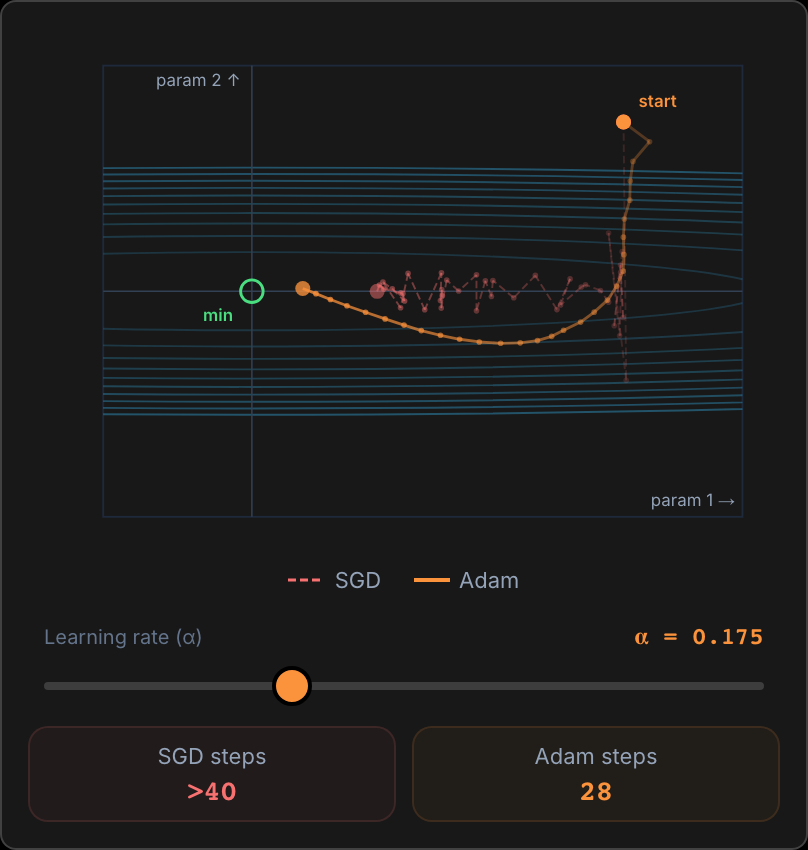
Comparison
Adam vs SGD: two ways down the same hill
2 min read
training pointone tree (a stump)all 20 trees combined
Comparison
Bagging vs boosting: many trees side by side or one after another
2 min read
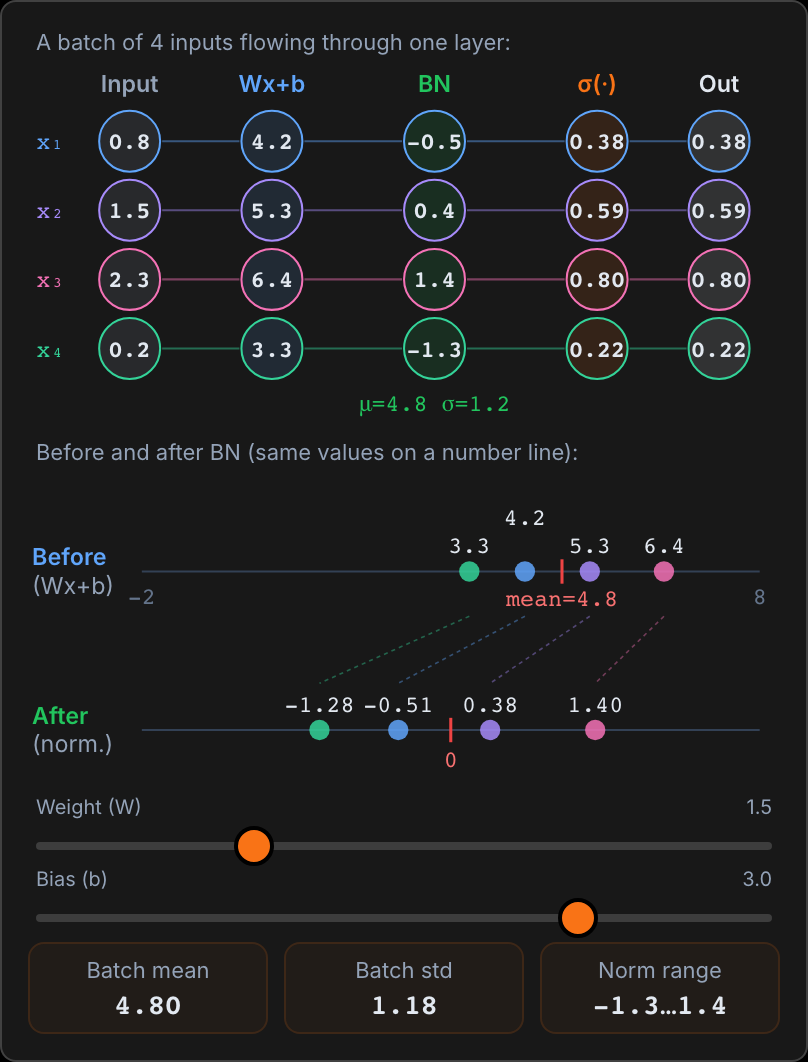
Plain words
Batch normalization in plain words
2 min read
one model (dart)average throwtrue answer
Comparison
Bias vs variance: the dartboard view
2 min read
answer spanchunk with most of the answer
Comparison
Chunk size: too small vs too big
2 min read
| from A to | distance | cosine | distance at length 1 |
|---|---|---|---|
| B | 2.06 | 1.000 | 0.00 |
| C | 1.80 | 0.901 | 0.45 |
Boxed: the nearer vector by each measure. Ringed dots: each vector divided by its length.
Comparison
Cosine vs Euclidean: why embeddings compare angles
2 min read
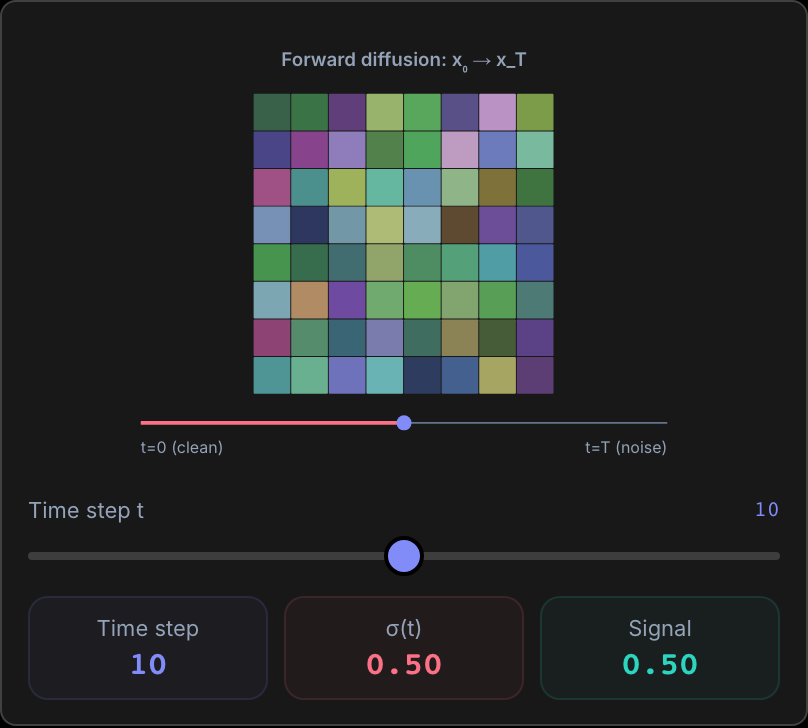
Plain words
Diffusion models in plain words: add noise, learn to remove it
2 min read
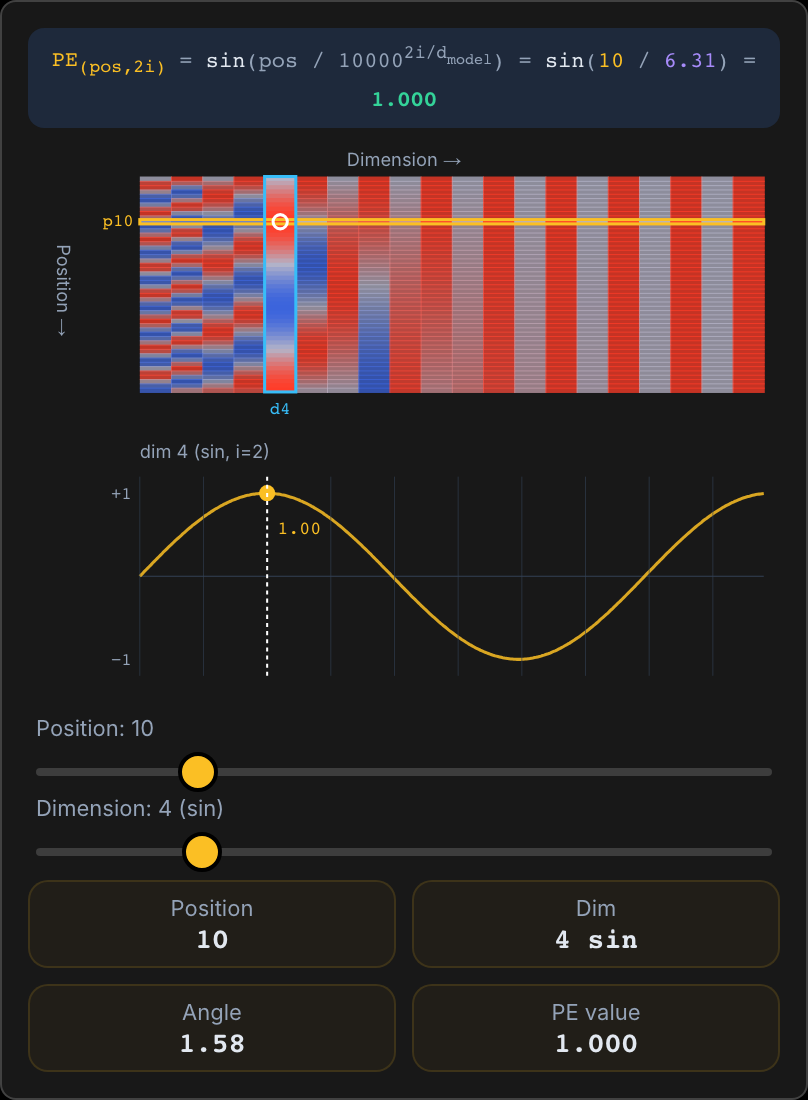
Plain words
How a transformer knows word order, in plain words
2 min read
frozen pretrained weighttrained LoRA matrices (outlined so they show)
Applied
How LoRA fine-tunes a 7B model by training 0.4% of a layer
2 min read
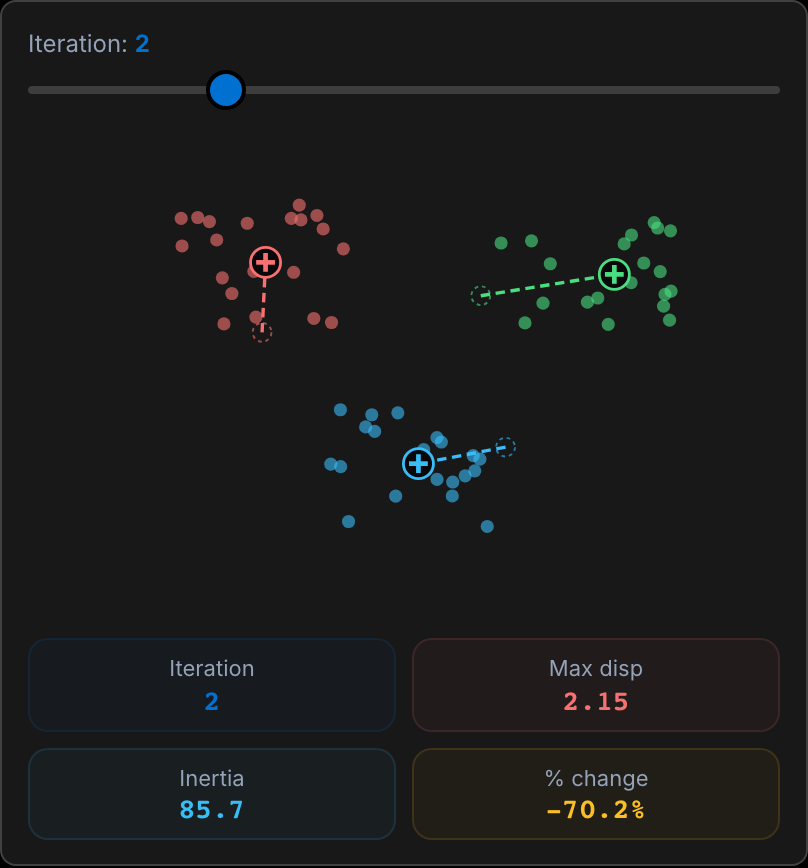
Plain words
K-means in plain words: guess, move, repeat
2 min read
loss contourallowed weightswhere it settles
Comparison
L1 vs L2: why only one sets weights to exactly zero
2 min read
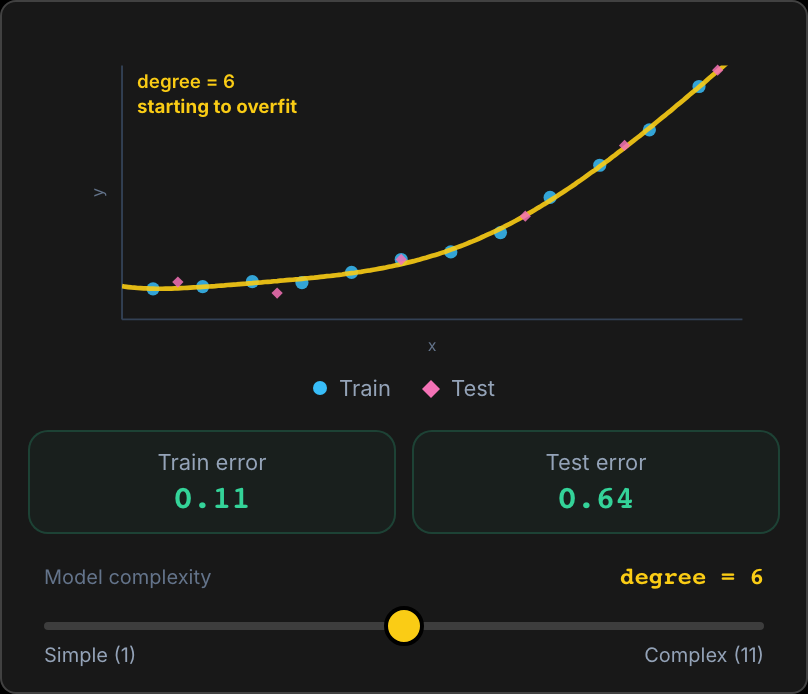
In 1 picture
Overfitting in 1 picture
2 min read
normal email (700)spam (300)false positivefalse negative
Comparison
Precision vs recall: one threshold, two kinds of mistake
2 min read
retrieval: embed, search, rerankgeneration: prefill, decode
In 1 picture
RAG latency in 1 picture
2 min read
where the new knowledge goesflow of data
Comparison
RAG vs fine-tuning: look it up or learn it in
2 min read
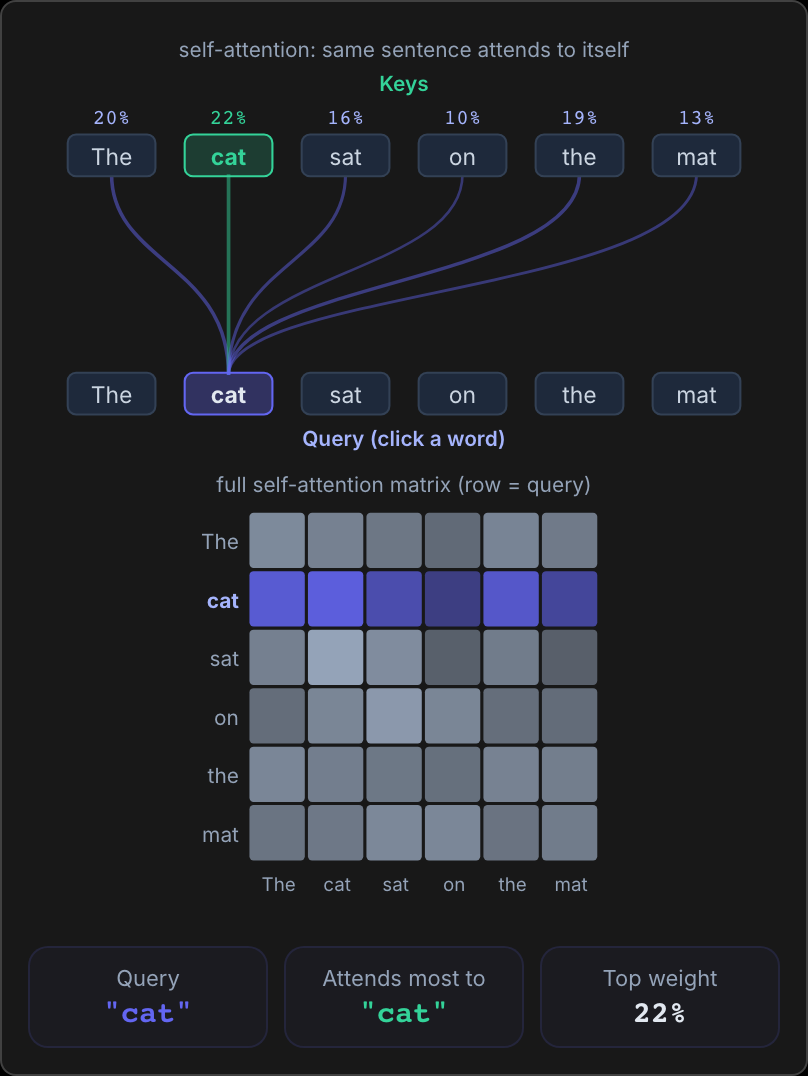
In 1 picture
Self-attention in 1 picture: every word looks at every word
2 min read
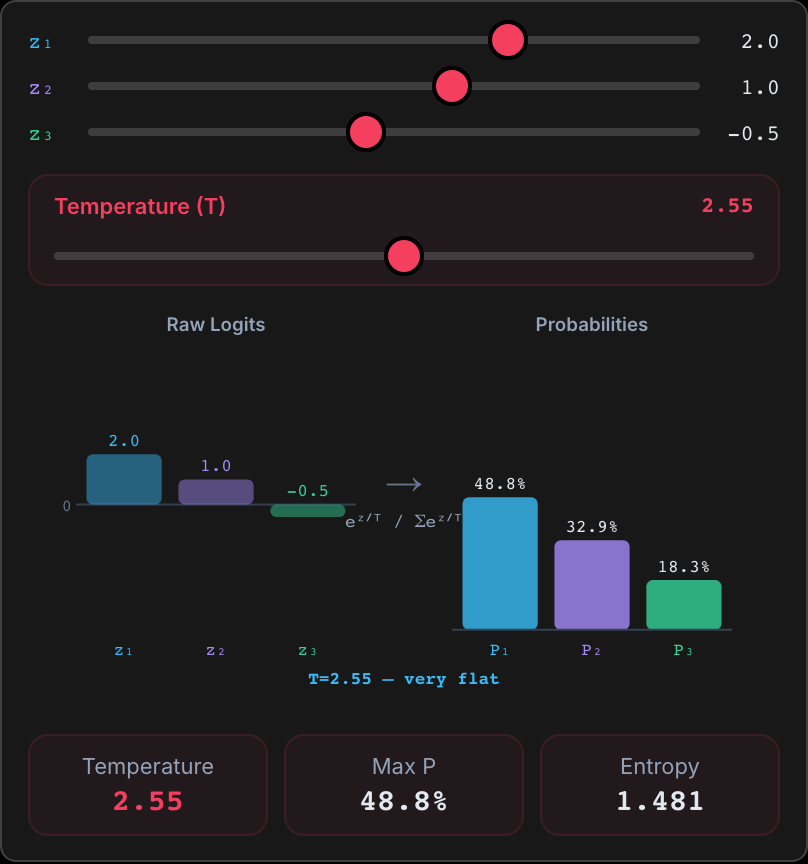
In 1 picture
Temperature in 1 picture: from confident to spread out
2 min read
Values in %. White ticks mark each T = 1 length; dashed boxes mark cut tokens.
Comparison
Temperature vs top-p: reshape every bar or cut the tail
2 min read
In 1 picture
The recommendation funnel in 1 picture
2 min read
frozen pretrained layersnew head, trained (outlined so it shows)
Block heights are schematic. The old 1,000-class head (2,049,000 weights) is removed.
Applied
Transfer learning: freeze 99.9% of a model, train a new last layer
2 min read
TN: normal, passedFP: false alarmFN: missed fraudTP: caught fraud
10,000 transactions, 100 of them fraud. Rows: actual class. Columns: the model's call.
Applied
Why 99% accuracy can mean a useless model
2 min read
10% exploration
round 40 click rate 42.1%
impression Gini 0.89
no exploration
round 40 click rate 46.2%
impression Gini 0.97
Applied
Why feeds get stuck on popular items
2 min read
In 1 picture
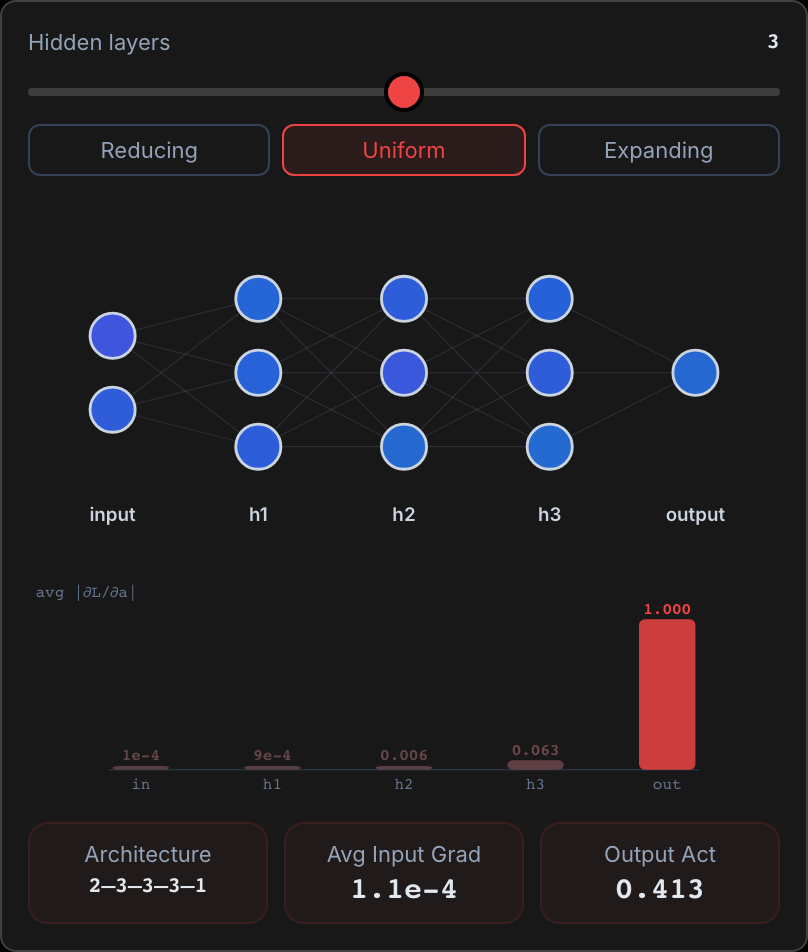
Why gradients vanish in deep networks, in 1 picture
2 min read
In 1 picture
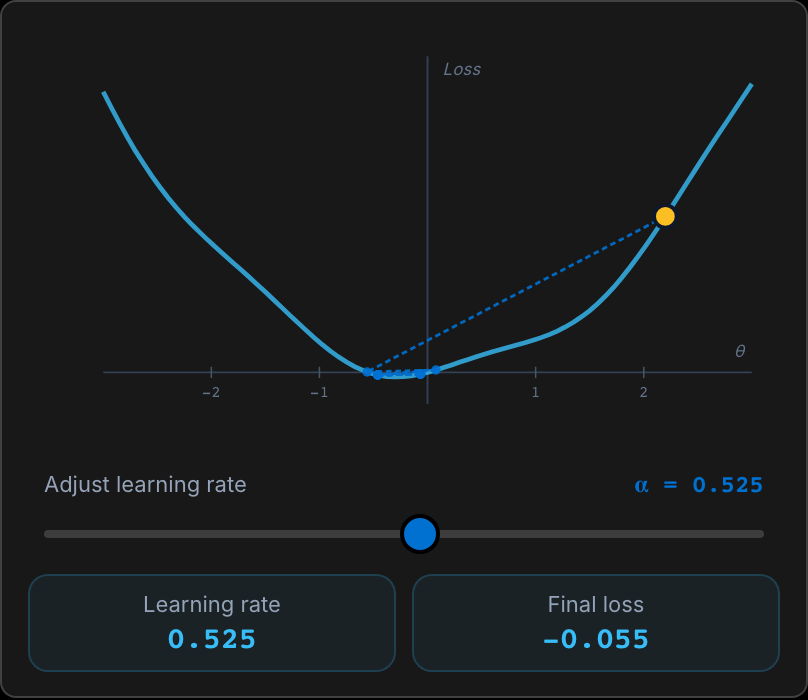
Why your loss bounces when the learning rate is too high
2 min read