What is the Transformer architecture?
The Transformer is a neural network architecture that processes a whole sequence at once, using attention to let every token look directly at every other token. It was introduced in the 2017 paper "Attention Is All You Need" (Vaswani et al.) for machine translation, and it is the foundation of almost every modern language model, including GPT, BERT, and T5.
Before Transformers, sequence models were mostly recurrent (RNNs and LSTMs): they read one token at a time and squeezed everything they had seen into a single hidden state. The Transformer drops recurrence entirely. That makes training highly parallel on GPUs, and it means information between two distant words travels in one step instead of many.
Key ideas
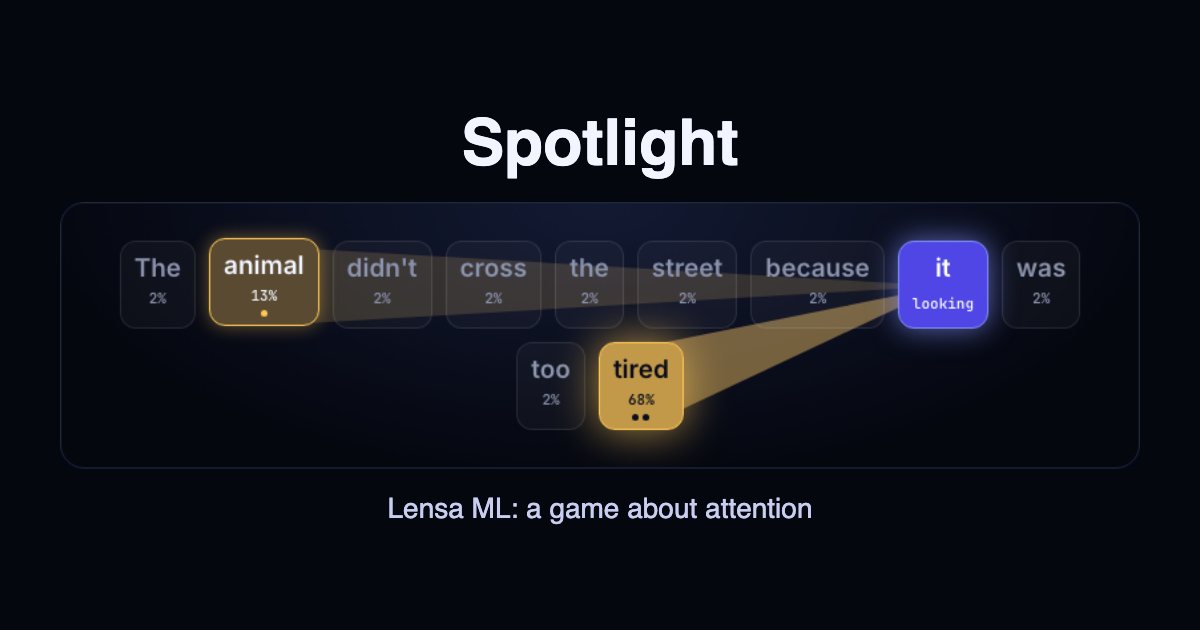
- Self-attention lets every token read every other token directly, in parallel.
- Attention(Q, K, V) = softmax(QKᵀ / √d_k) · V: scores from queries and keys, a weighted sum of values.
- Multiple heads learn different relationships at about the cost of one.
- Positional encodings put word order back in, because attention alone ignores it.
- Residual connections and layer normalization make deep stacks trainable.
- Encoder-only (BERT) and decoder-only (GPT) models are both built from these blocks.
Common questions
What does the feed-forward layer do?
After attention mixes information between positions, each block applies the same small two-layer network to every position separately: expand from 512 to 2,048 dimensions, apply ReLU, and project back to 512. In each encoder block this feed-forward layer holds about two-thirds of the weights.
How many parameters does the original Transformer have?
The base model in the paper has about 65 million parameters and the big model about 213 million. Modern large language models use the same building blocks at a much larger scale, with billions of parameters.
Is GPT a Transformer?
Yes. GPT keeps only the decoder half: masked self-attention and feed-forward blocks, without cross-attention, trained to predict the next token. BERT keeps only the encoder half and is trained to fill in masked words.
Why is attention O(n²)?
Every token computes a score against every other token, so a sequence of n tokens needs an n × n score matrix in each head and layer. This is why long contexts are expensive and why efficient-attention variants exist.
Related explainers
- How Self-Attention Works — Query, key, value — the core of self-attention
- Multi-Head Attention — Parallel attention heads learning different patterns
- Positional Encoding — How transformers know word order
- Cross-Attention — Attending across sequences and modalities
- Decoder-Only Transformers — The architecture behind GPT and modern LLMs
- BERT & Masked Language Modeling — Mask a word, predict it from both sides — how BERT learns deep bidirectional representations
References
- Vaswani et al. (2017), "Attention Is All You Need", NeurIPS
- Bahdanau, Cho & Bengio (2014), "Neural Machine Translation by Jointly Learning to Align and Translate"
- Ba, Kiros & Hinton (2016), "Layer Normalization"
- Su et al. (2021), "RoFormer: Enhanced Transformer with Rotary Position Embedding"
- Ainslie et al. (2023), "GQA: Training Generalized Multi-Query Transformer Models from Multi-Head Checkpoints"
- He et al. (2016), "Deep Residual Learning for Image Recognition", CVPR
Last updated
 Spotlight