Lensa ML

Gradient Descent

Step 1 of 6: A Model and Its Loss

Fit a line to 10 houses and see the valley

price ~ θ · areaarea (100 m²)loss L(θ)0123
Slope θ0.40
θ
0.40
Loss (mean squared error)
3.430
Best possible loss
0.073

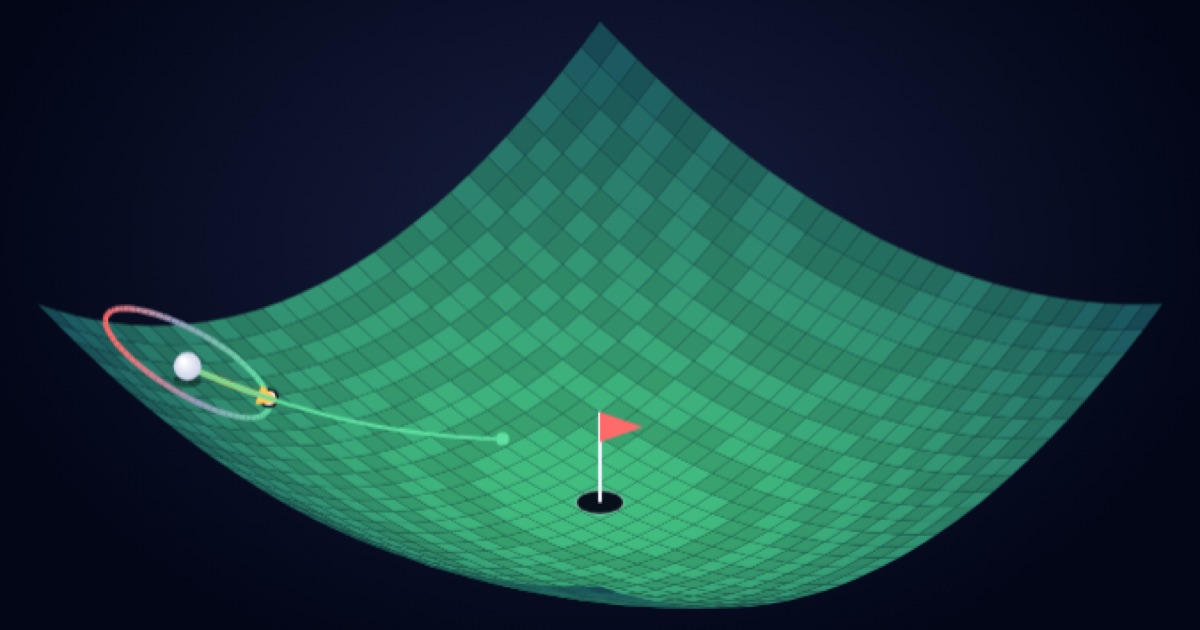
The model guesses price = θ × area for 10 houses. Each red line is one house's error, and the loss is the average squared error: 3.430 at θ = 0.40. The right panel plots that loss for every θ: a valley with its bottom at θ = 1.77 (green). Training means finding that bottom. Here you can see the whole curve, but a real network has millions of parameters and can only feel the slope where it stands, like walking downhill in fog.

Drag θ and watch both panels. The loss here is the mean squared error over 10 houses, a parabola in θ because the model is linear, so it has exactly one minimum. That minimum even has a closed form, θ* = Σxy / Σx². Neural networks have no such formula and millions of parameters, so mapping the loss is impossible: checking just 10 values for each of a million parameters would take 10 to the millionth evaluations. Gradient descent needs only local information, the slope at the current point. Augustin-Louis Cauchy described the method in 1847.

Step 2 of 6: Follow the Slope

Step against the gradient, in proportion to it

price ~ θ · areaarea (100 m²)loss L(θ)0123
Slope θ0.30
Gradient dL/dθ
-5.263
Step −0.1 × gradient
+0.526
Loss now → after
3.938 → 1.665

The gradient is the slope of the loss where you stand: dL/dθ = 2·mean(x·(θx − y)) = -5.263. It's negative, so the loss falls if θ increases, and the step points right. Gradient descent moves against it, θ ← θ − α·∇L. The green arrow is that step with α = 0.1. Its length is proportional to the slope, so steps are big on steep ground and shrink automatically near the bottom. Click the step button a few times.

Move θ, then take steps. The gradient is the derivative of the loss with respect to each parameter; backpropagation computes it for every weight of a network at about the cost of one extra forward pass. Because the step is α times the gradient, it is large on steep slopes and shrinks as the slope flattens, so plain gradient descent slows down near a minimum by itself, with no extra rule.

Step 3 of 6: The Learning Rate

Crawl, converge, or blow up

price ~ θ · areaarea (100 m²)loss L(θ)0123
Learning rate α0.20
2/L'' = 0.56
α × curvature
0.72
Steps to converge
5
Loss after 12 steps
0.073

At α = 0.20 every step moves the same way and lands short of the bottom. It converges in 5 steps. The fastest choice here is α = 1/curvature = 0.28, which reaches the bottom of a quadratic in one step. Drag α up and find where it starts to zig-zag, and where it blows up.

Drag the learning rate across the coloured bar. For a quadratic loss with curvature L'', a step multiplies the distance to the minimum by (1 − α·L''): below α = 1/L'' it approaches from one side, between 1/L'' and 2/L'' it zig-zags in, and above 2/L'' it diverges. Real losses are not quadratic, but the same picture holds locally, with L'' replaced by the largest curvature. That's why practitioners tune the learning rate first, use a short warm-up, and treat a sudden loss spike as a sign the rate is too high.

Step 4 of 6: Step by Step

Watch the line fit itself

price ~ θ · areaarea (100 m²)loss L(θ)0123
Step
0 / 25
θ
0.200
Loss
4.4827
Gradient
-5.621

Each click is one training step: compute the gradient on all 10 houses, move θ against it. Watch the line in the left panel swing toward the data while the dot slides down the valley. Press play.

Pick a learning rate and step through. Each step uses all 10 houses to compute the exact gradient, which is called batch gradient descent. With the good rate the loss drops by a constant factor each step (linear convergence) until it reaches the best possible fit. Optimizers such as momentum and Adam change only how each step is computed from the gradient; the loop of compute gradient, update, and repeat stays the same.

Step 5 of 6: In Two Dimensions

Long thin valleys, and how centring fixes them

w →bbrighter = lower loss · ○ = best fit
Learning rate α0.30
Condition number λmax/λmin
32.0
Divergence edge 2/λmax
0.37
Steps to converge
> 60

With raw areas, w and b pull in almost the same direction, so the loss is a long thin valley: it is 32 times steeper across than along. The learning rate has to stay below 0.37 for the steep direction, which makes progress along the flat floor painfully slow: after 60 steps it still hasn't arrived. Switch to centred x.

Switch between raw and centred areas and push the learning rate. With two parameters the loss is a bowl, and its curvature differs by direction. The ratio of the steepest to the flattest curvature, the condition number, controls how slowly gradient descent converges: the step must be small enough for the steepest direction, so progress along the flattest one crawls. Centring and scaling inputs, momentum, and adaptive optimizers such as Adam all exist largely to fight this problem.

Step 6 of 6: Stochastic & Mini-Batch

Cheap noisy steps vs exact expensive ones

0500100015002000per-house gradients computed (cost)loss (log scale) · dashed = best possible
━ SGD, batch 1━ mini-batch 20━ full batch, 200
Batch 1: steps · loss at 200 evals
2000 · 0.028
Batch 20: steps · loss at 200 evals
100 · 0.072
Batch 200: steps · loss at 200 evals
10 · 1.161

A real dataset can have millions of rows, so computing the exact gradient for one step is expensive. Here 200 houses: full-batch gradient descent spends all 200 per-house gradients on each step and gets only 10 steps out of a budget of 2000. A mini-batch of 20 estimates the gradient from 20 random houses, a noisy but unbiased estimate, and gets 100 steps. After the first 200 evaluations the losses are 1.161 (full), 0.072 (batch 20) and 0.028 (batch 1): cheap noisy steps make progress sooner. Batch 1 stays jittery near the bottom because its noise never averages out at a fixed learning rate, which is why training usually decays the rate.

Reshuffle and compare the three curves against cost, not steps. Stochastic gradient descent estimates the gradient from a random sample of examples; the estimate is unbiased, and its noise shrinks like 1/√(batch size). For a fixed compute budget, small batches make far more updates, which usually wins early. Very small batches waste parallel hardware and stay noisy near the minimum, so practice uses mini-batches of tens to thousands of examples and a decaying learning rate.

What is gradient descent?

Gradient descent is an iterative method for finding the minimum of a function. At each step it computes the gradient, the direction in which the function rises fastest, and moves the parameters a small step the opposite way. The update rule is θ ← θ − α∇L(θ), where α is the learning rate.

Almost every neural network is trained with some form of gradient descent, from small classifiers to large language models. Backpropagation supplies the gradient of the loss with respect to each weight, and gradient descent uses it to update the weights. Variants such as SGD with momentum and Adam change how the step is computed, but they all follow the same downhill idea.

Key ideas

  • Gradient descent repeatedly moves the parameters opposite the gradient of the loss.
  • The learning rate sets the step size; too large diverges, too small crawls.
  • Steps shrink near a minimum because the gradient shrinks.
  • Long, narrow valleys make plain gradient descent zigzag.
  • Mini-batches trade a noisier gradient for much cheaper steps.
  • On non-convex losses it finds a good low point, not necessarily the global minimum.

Short takes on this topic

Common questions

Does gradient descent always find the global minimum?

Only on convex functions, such as the loss of linear or logistic regression, with a suitable learning rate. Neural network losses are not convex, so gradient descent can stop at a local minimum or slow down near a saddle point. In practice, the minima it finds in large networks tend to work well.

How do you choose a learning rate?

A common approach is a learning rate range test: train briefly while raising the rate exponentially, then pick a value a little below where the loss starts to blow up. Typical starting points are around 0.1 for SGD with momentum and 0.001 for Adam. Most training runs then lower the rate over time with a schedule.

Why is it called stochastic gradient descent?

Each step uses a randomly chosen example or mini-batch instead of the full dataset, so the gradient is a random estimate of the true one. In modern usage, SGD almost always means mini-batch gradient descent. Shuffling the data each epoch keeps the batches representative.

What is the difference between gradient descent and Adam?

Plain gradient descent moves every parameter by the same learning rate times its gradient. Adam keeps running averages of each parameter's gradient and squared gradient, which adds momentum and scales the step separately for every parameter. That helps on loss surfaces with very different curvature in different directions.

Related explainers

References

  1. Goodfellow, Bengio & Courville (2016), "Deep Learning", section 4.3: Gradient-Based Optimization
  2. Stanford CS231n, "Optimization: Stochastic Gradient Descent"
  3. Ruder (2016), "An overview of gradient descent optimization algorithms"
  4. Smith (2017), "Cyclical Learning Rates for Training Neural Networks"

Last updated