What is the bias-variance tradeoff?
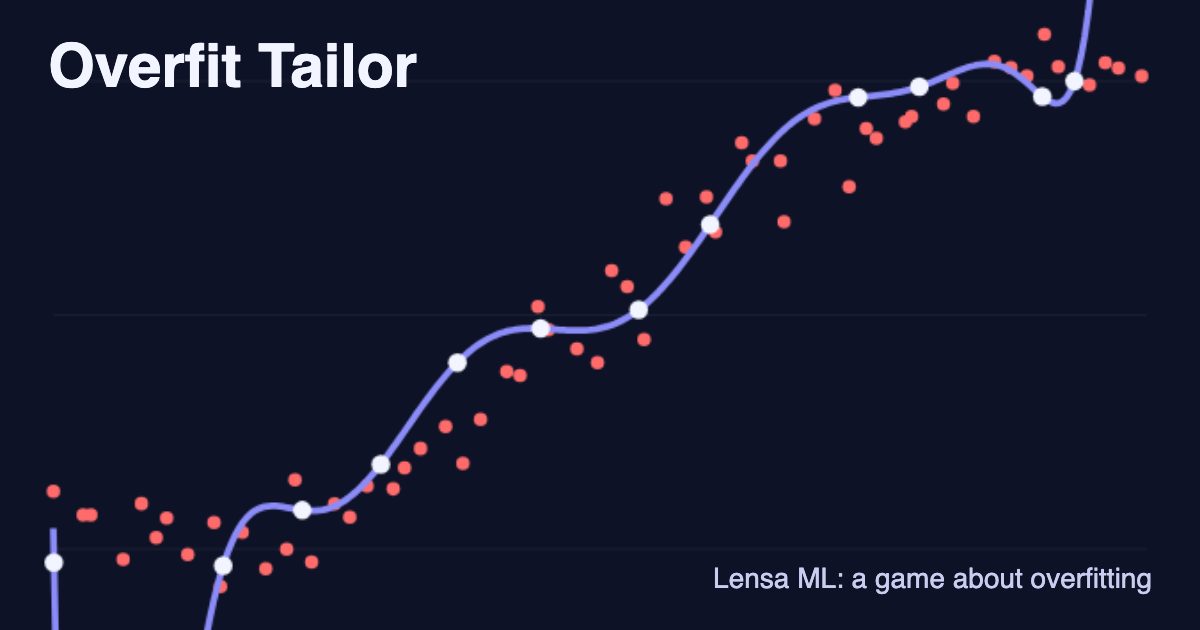
The bias-variance tradeoff describes how a model's expected test error splits into two competing sources. Bias is the error from a model being too rigid to represent the true pattern; variance is the error from a model being so flexible that its fit changes with every new training sample. Making a model more complex usually lowers bias and raises variance, so total error is lowest somewhere in between.
The idea guides most choices about model capacity: polynomial degree, tree depth, the number of neighbors in k-NN, the strength of L2 regularization, and the size of a neural network. It also explains why ensembles work. Bagging and random forests average many high-variance models to cut variance, while boosting adds weak, high-bias learners one at a time to cut bias.
Key ideas
- Expected squared test error equals bias² plus variance plus irreducible noise.
- Bias measures how far the average model is from the truth, across many training sets.
- Variance measures how much the fitted model changes from one training set to the next.
- More data lowers variance but leaves bias unchanged.
- Regularization and averaging reduce variance at the cost of a small increase in bias.
- The best complexity is chosen with validation data, because bias and variance cannot be measured directly.
Short takes on this topic
Common questions
Is high bias the same as underfitting?
They describe the same situation from two angles. High bias is the cause, a model class too rigid for the pattern, and underfitting is the symptom, high error on both the training and validation data. Likewise, high variance is the cause of overfitting.
Can a model have both high bias and high variance?
Yes. A model that is the wrong shape for the data and is also trained on very few, noisy examples can miss the pattern on average and still swing a lot between samples. A deep decision tree trained on inputs unrelated to the target is one example.
How does k in k-nearest neighbors affect bias and variance?
Small k gives low bias and high variance: with k = 1, each prediction copies a single neighbor, noise included. Large k averages more neighbors, which smooths the prediction and lowers variance, but it blurs real boundaries and raises bias. At k = n, every input gets the same prediction.
How do you estimate bias and variance in practice?
Variance can be estimated by training the same model on many bootstrap resamples and measuring how much the predictions spread at each test point. Bias needs the true function, so on real data it is approximated by subtracting that variance and a noise estimate from the measured test error. Simulations with a known function, like the sine wave here, give exact values.
Related explainers
- Overfitting & Underfitting — The bias-variance tradeoff and generalization
- Regularization — Dropout, L1, and L2 — keeping models honest
- Cross-Validation — K-fold, stratified, and leave-one-out evaluation
- Learning Curves — Diagnosing underfitting and overfitting from training size
- Bagging & Random Forests — Bootstrap aggregation and decorrelated tree ensembles
- Gradient Boosting — Sequential residual fitting for powerful predictions
References
- Geman, Bienenstock & Doursat (1992), "Neural Networks and the Bias/Variance Dilemma", Neural Computation
- Belkin, Hsu, Ma & Mandal (2019), "Reconciling modern machine learning practice and the bias-variance trade-off", PNAS
- Nakkiran et al. (2019), "Deep Double Descent: Where Bigger Models and More Data Hurt"
- James, Witten, Hastie & Tibshirani, "An Introduction to Statistical Learning", ch. 2
Last updated
 Overfit Tailor